
Building an RL fine-tuning platform to train JEV-like decision models
文章目录
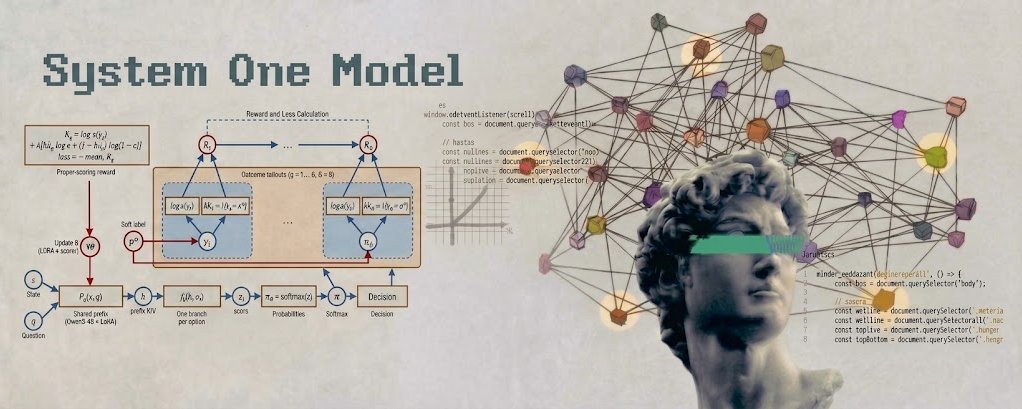
This article walks through how we built a small training platform that turns a normal open LLM (Qwen3-4B) into a decision model.
The result is Gero-4B, and everything below is the code we actually used, simplified a bit so it is easier to follow.
We used Apple's MLX on a MacBook (M5 Pro, 24 GB), but the ideas work in PyTorch too.
What we want the model to do
A decision model answers questions like these:
-
Choice: "Which team should handle this ticket?" with options billing, technical, account, shipping.
-
Score: "How severe is this problem?" with ordered levels from "cosmetic" to "everyone is blocked".
-
Yes/no: "Is the customer happy?"
And instead of writing "I think it is billing", it returns something like:
{"billing": 0.974, "technical": 0.011, "account": 0.010, "shipping": 0.005}
Two things matter here:
-
The output is numbers, so your code can use it directly. No parsing, no "the model replied in the wrong format".
-
The numbers should be honest. If the model says 0.9, it should be right about 9 times out of 10. This is called being calibrated, and it is the whole reason to build this. Calibrated confidence lets you say "auto-handle anything above 0.95, send the rest to a human".
Normal chat LLMs are bad at point 2. Ask them how sure they are and they will happily say 95% about things they get wrong half the time.
The plan: three stages
We split the work into three stages, and each stage has exactly one job:
| Stage | Job | What it should NOT do |
|---|---|---|
| 1. Architecture | Change the model so it scores options instead of writing text | |
| 2. Structure training | Teach it to read the question format | Teach real-world knowledge |
| 3. RL training | Teach it to make calibrated decisions | Re-teach the format |
Keeping the jobs separate sounds like a small thing, but it saved us many times. When something broke, we knew which stage to look at.
Setup
pip install mlx mlx-lm
import json
import mlx.core as mx
import mlx.nn as nn
from mlx_lm import load
from mlx_lm.tuner import linear_to_lora_layers

model, tok = load("mlx-community/Qwen3-4B-4bit")   # 4-bit so it fits in 24 GB
model.freeze()                                        # base weights stay frozen
linear_to_lora_layers(model, 8, {"rank": 16, "scale": 8.0, "dropout": 0.0})
We only train small LoRA adapters on the last 8 layers. The base model already knows a lot about language. We just want to change how it answers, not what it knows.
Step 1: The prompt format
Every question becomes a prefix (the context) plus one branch per option:
SYSTEM = "Judge how well the Option answers the Question, given the State."

def render(state, question, options):
    if not isinstance(state, str):
        state = json.dumps(state, ensure_ascii=False)
    prefix = ("<|im_start|>system\n" + SYSTEM + "<|im_end|>\n"
              "<|im_start|>user\n<State>: " + state + "\n<Question>: " + question + "\n")
    branches = [f"<Option>: {o}<|im_end|>" for o in options]
    return prefix, branches
Notice that the list of options is not written into the prefix. Each option only lives in its own branch. That is on purpose and it is the key idea of the next step.
For yes/no questions the two options are just the "no" text and the "yes" text, in that order. For choice options with a description, we write them as "billing - payments, invoices and refunds".
Step 2: Turn the LLM into a scorer (the branch readout)
Our first try, and why it failed
Our first idea was simple: put all the options in the prompt, numbered, and add a classification head with 256 outputs, one per option slot. Option 1 is slot 0, option 2 is slot 1, and so on.
It looked fine until we tested more than 6 options. Then accuracy fell apart. When we looked at the head's weights, we found out why: rows 6 to 255 were basically still at their random starting values. Our training data almost never had more than 6 options, so those slots never got trained. A model with 256 slots that only learned 6 of them.
It also had a second problem: listing options in order means the model can learn "the answer is usually near the top". That is position bias, and it ruins calibration.
The fix: one shared scorer, one branch per option
Instead of slots, we:
-
Remove the LM head completely.
-
Add one tiny linear layer, Linear(2560, 1), that turns a hidden state into a single score.
-
Run the prefix once, then run every option as its own branch that can look at the prefix but not at the other options.
-
Read the score from the last token of each branch, and softmax across the branches.
class Gero(nn.Module):
    def __init__(self, backbone, hidden=2560):
        super().__init__()
        self.backbone = backbone
        self.scorer = nn.Linear(hidden, 1, bias=False)
        # Hidden states have a norm around 300, so 1e-3 gives scores spread
        # around 0.3: close to uniform at the start, but not so tiny that
        # gradients die.
        self.scorer.weight = mx.random.normal(self.scorer.weight.shape) * 1e-3

m = Gero(model)
Now the trick for running branches efficiently. MLX layers take a cache object with an update_and_fetch(k, v) method. We write two small cache classes. The first one records the prefix keys and values. The second one hands that same prefix to every branch.
class Record:
    """Prefix pass: remember this layer's keys and values."""
    def __init__(self):
        self.offset = 0
    def update_and_fetch(self, k, v):
        self.k, self.v = k, v
        self.offset += k.shape[2]
        return k, v

class SharePrefix:
    """Branch pass: every branch sees the same prefix keys and values."""
    def __init__(self, rec):
        self.pk, self.pv, self.offset = rec.k, rec.v, rec.offset
    def update_and_fetch(self, k, v):
        B = k.shape[0]                      # number of branches
        pk = mx.broadcast_to(self.pk, (B,) + self.pk.shape[1:])
        pv = mx.broadcast_to(self.pv, (B,) + self.pv.shape[1:])
        return mx.concatenate([pk, k], 2), mx.concatenate([pv, v], 2)

def run(backbone, ids, mask, caches):
    t = backbone.model
    h = t.embed_tokens(ids)
    for layer, c in zip(t.layers, caches):
        h = layer(h, mask, c)
    return t.norm(h)

def branch_logits(m, pre_ids, opt_ids):
    recs = [Record() for _ in m.backbone.model.layers]
    run(m.backbone, mx.array([pre_ids]), "causal", recs)      # prefix, once

    P, Lb = len(pre_ids), max(len(o) for o in opt_ids)
    ids = mx.array([o + [0] * (Lb - len(o)) for o in opt_ids])  # pad branches
    r = mx.arange(Lb)
    mask = mx.concatenate([mx.ones((Lb, P), dtype=mx.bool_),   # see all of the prefix
                           r[:, None] >= r[None, :]], axis=1)  # causal inside the branch
    h = run(m.backbone, ids, mask, [SharePrefix(x) for x in recs])

    last = mx.array([len(o) - 1 for o in opt_ids])
    return m.scorer(h[mx.arange(len(opt_ids)), last].astype(mx.float32)).squeeze(-1)
The mask is the important part. Each branch row can see:
            prefix tokens        its own tokens
branch A:   [1 1 1 1 1 1 1 1]    [causal]
branch B:   [1 1 1 1 1 1 1 1]    [causal]      <- but never A's tokens
Because the branches are separate rows in a batch, option B physically cannot see option A. Padding at the end of a short branch does not matter either, since we read the score from the last real token and the mask is causal.
What we get from this design:
-
No position bias, by construction. Shuffle the options and every score stays exactly the same. We tested this: the max difference was 0.0.
-
Any number of options. One shared scorer means 2 options and 256 options use the same weights. No untrained slots.
-
Cheap. The prefix (usually the long part) is computed once, no matter how many options there are.
The options still compete with each other, through the softmax. They are scored separately, but trained together.
A quick sanity test you should always run:
pre, brs = render("Charged twice for my invoice.", "Which team?", ["billing", "technical", "shipping"])
enc = lambda s: tok.encode(s, add_special_tokens=False)
a = mx.softmax(branch_logits(m, enc(pre), [enc(b) for b in brs]))
b = mx.softmax(branch_logits(m, enc(pre), [enc(b) for b in reversed(brs)]))
print(a, b[::-1])   # should be identical
Step 3: Stage 2 data, teaching the format without teaching content
Stage 2 has one job: teach the model to read the question format correctly. Many options, ordered scales, yes/no with different wordings, negation.
Our first version of Stage 2 used real datasets (news topics, sentiment, and so on). It worked, but the model was learning two things at once: the format and the content. When something went wrong we could not tell which part was broken.
So we switched to content-free data. Made-up crates, shelves and codes like QX-417A that mean nothing. The only way to get the answer is to actually read the state and the question.
Here is a simplified version of our yes/no generator:
import random

NOUL_OPTS = [("no", "yes"), ("false", "true"), ("incorrect", "correct")]

def make_yes_no(R, i):
    n = R.randint(2, 8)
    shelves = R.sample(range(1, 100), n)
    items = [f"{R.choice(['QX','FJ','RT','ZP'])}-{R.randint(100,999)}{R.choice('ABCDEFG')}" for _ in range(n)]
    ask = R.randrange(n)

    truth = (i % 2 == 0)                         # exactly 50/50 on the fact
    # the wrong item is taken from ANOTHER shelf in the same state,
    # so "is this code in the text?" never gives away the answer
    probe = items[ask] if truth else items[(ask + 1) % n]
    negated = (i // 2) % 2 == 1                  # exactly 50/50 on negation

    if negated:
        q = f"Is it false that shelf {shelves[ask]} holds {probe}?"
    else:
        q = f"Does shelf {shelves[ask]} hold {probe}?"
    state = "Manifest: " + "; ".join(f"shelf {s} holds {it}" for s, it in zip(shelves, items)) + "."
    no, yes = R.choice(NOUL_OPTS)
    return dict(state=state, question=q, options=[no, yes], target=int(truth != negated))
Look at the small details, because each one fixes a real bug we had:
-
The fact is exactly 50/50, and so is negation. If "yes" is right 60% of the time, the model just learns to say yes.
-
The wrong answer comes from the same state. In an early version the wrong code was random, so "is this code mentioned anywhere?" solved the question without reading. The model found that shortcut immediately.
-
The yes/no wording changes (no/yes, false/true, incorrect/correct) so the model cannot memorize one word.
We wrote similar generators for choice questions (1 to 256 options, sampled log-uniformly so big lists actually show up), score questions (2 to 10 ordered levels, balanced over levels), and some reading skills: negation, "is this actually stated?", and binding the right attribute to the right thing.
The negation shortcut (a mistake worth knowing about)
At one point we added a lot of negated questions to fix negation. Training accuracy went up and we were happy. Then accuracy on a real entailment task dropped from 0.775 to 0.617.
What happened: in our data, negation words like "not" and "false" only ever showed up in negated questions. So the model learned "if I see a negation word, flip the answer". On real text, negation words appear everywhere, in the state, in normal questions, and the model was flipping answers that should not be flipped.
The fix was to decorrelate: put negation words in states and in normal questions too, so the word alone tells you nothing.
Step 4: Check the data before you train on it
This was the biggest lesson of the whole project. We wasted more time on bad data than on anything else. So we wrote a checker that runs before every training run and refuses to continue if something looks wrong.
Here are some of the checks:
from collections import Counter

def check_leak(train, holdout):
    """Train and holdout must not share a state, not just an index."""
    seen = {json.dumps(e["state"], sort_keys=True) for e in train}
    leaked = [e for e in holdout if json.dumps(e["state"], sort_keys=True) in seen]
    assert not leaked, f"{len(leaked)} holdout states also appear in train"

def check_position(data):
    """The right answer should not prefer one position."""
    for k in {e_k for e_k in (len(e["options"]) for e in data) if e_k <= 6}:
        rows = [e for e in data if len(e["options"]) == k]
        top = Counter(e["target"] for e in rows).most_common(1)[0][1] / len(rows)
        assert top < 1 / k + 0.10, f"k={k}: one slot holds {top:.0%} of answers"

def check_majority_text(data):
    """If always picking the same option TEXT scores well, the item can be solved without reading."""
    gold = Counter(e["options"][e["target"]] for e in data)
    worst = gold.most_common(1)[0][1] / len(data)
    assert worst < 0.6, f"answer text '{gold.most_common(1)[0][0]}' is right {worst:.0%} of the time"

def check_string_presence(data):
    """'Pick whichever option appears in the state' must not work."""
    solved = 0
    for e in data:
        hits = [i for i, o in enumerate(e["options"]) if o in json.dumps(e["state"])]
        solved += hits == [e["target"]]
    assert solved / len(data) < 0.05, f"string presence solves {solved/len(data):.0%}"
The last one is sneaky. In our choice data, the right item was always written in the state and the wrong ones were random codes. "Pick the option that appears in the text" solved almost everything. Taking distractors from the same state fixed it.
And always test your checks on purpose: make a dataset with a known leak and confirm the checker catches it. A checker that never fails might just be broken.
Step 5: Stage 2 training
The loss is plain cross-entropy against the target distribution. We use soft targets (a full probability list) instead of a single index, because Stage 3 needs that anyway.
def stage2_loss(model, batch):
    total = 0.0
    for e in batch:
        logits = branch_logits(model, e["pre_ids"], e["opt_ids"])
        logp = logits - mx.logsumexp(logits)
        target = mx.array(e["soft"])            # one-hot for normal items
        total = total - (target * logp).sum()
    return total / len(batch)
Two optimizers, and why scaling gradients does not work
The scorer is brand new and needs a bigger learning rate than the LoRA weights. Our first attempt was to multiply the scorer's gradients by 20. That does nothing with Adam.
Adam divides each gradient by a running estimate of its own size. If you multiply the gradient by 20, that estimate also grows by 20, and they cancel out. So our "20x learning rate" was a no-op for a whole run. The real fix is two optimizers:
import mlx.optimizers as optim

opt_scorer = optim.AdamW(learning_rate=5e-4)
opt_lora = optim.AdamW(learning_rate=3e-5)
step_fn = nn.value_and_grad(m, stage2_loss)

for step in range(steps):
    batch = rng.sample(train, 8)
    loss, g = step_fn(m, batch)
    g, _ = optim.clip_grad_norm(g, 1.0)
    p = m.trainable_parameters()
    m.update(opt_scorer.apply_gradients({"scorer": g["scorer"]}, {"scorer": p["scorer"]}))
    m.update(opt_lora.apply_gradients({"backbone": g["backbone"]}, {"backbone": p["backbone"]}))
    mx.eval(m.parameters(), opt_scorer.state, opt_lora.state)
When is Stage 2 done?
We set an exit rule: every structure family has to reach 0.98 accuracy on held-out items, and accuracy on real tasks must not drop. The second part matters. It is easy to get perfect on made-up crates and quietly break real reading.
Also save checkpoints often. We once killed a run that was not improving and lost the only checkpoint it had. Now we save every 150 steps.
Step 6: Stage 3, the RL reward
This is the part that makes it a decision model. The goal is: the model's probabilities should match how often it is actually right.
What is a proper scoring rule?
Imagine a coin that lands heads 70% of the time. You have to report a probability, and you get rewarded based on the actual flip. A reward is called proper if your best strategy is to report the truth, 0.7. Not 1.0 to look confident, not 0.5 to play it safe.
Log score (log p of what actually happened) is proper. So is the Brier score. If your reward is not proper, RL will happily find a way to cheat it.
The obvious reward is broken
The first reward we thought of sounds reasonable:
Let the model pick an answer. Reward it for how well its confidence in that answer predicted whether it was right.
Here is that idea as code, written as an exact expected value so we can see where training ends up:
truth = mx.array([0.174, 0.261, 0.005, 0.001, 0.141, 0.418])   # true answer odds

def naive_loss(z):
    p = mx.softmax(z)
    c = mx.clip(p, 1e-6, 1 - 1e-6)
    # choose option a with prob p(a), score how well p(a) predicts "a is right"
    per_choice = truth * mx.log(c) + (1 - truth) * mx.log1p(-c)
    return -(p * per_choice).sum()
Run gradient descent on it and look where it settles:
truth  [0.174, 0.261, 0.005, 0.001, 0.141, 0.418]
naive  [0.200, 0.181, 0.208, 0.208, 0.202, 0.001]
The right answer (0.418) gets pushed down to 0.001. The model found a cheat: pick an option that is almost certainly wrong, say "I am not confident", and you score well on calibration. It is perfectly "calibrated" and completely useless.
Our reward
We split it into two parts that are both proper:
-
Full distribution: sample real outcomes from the item's true answer distribution and reward log p(outcome). This pushes the whole distribution toward the truth.
-
Decision calibration: look at the model's top answer and its confidence c. Reward log c when the sampled outcome matches it and log(1 - c) when it does not. This makes the confidence of the actual decision honest.
def rl_loss(logits, soft, G, rng, lam=1.0):
    logp = logits - mx.logsumexp(logits)
    k = len(soft)
    outcomes = rng.choices(range(k), weights=soft, k=G)   # G sampled outcomes

    top = int(mx.argmax(logp).item())
    c = mx.clip(mx.exp(logp[top]), 1e-6, 1 - 1e-6)

    full = mx.stack([logp[y] for y in outcomes]).mean()
    hit_rate = sum(1 for y in outcomes if y == top) / G
    calib = hit_rate * mx.log(c) + (1 - hit_rate) * mx.log1p(-c)
    return -(full + lam * calib)
Same test as before:
truth  [0.174, 0.261, 0.005, 0.001, 0.141, 0.418]
ours   [0.174, 0.261, 0.005, 0.001, 0.141, 0.418]
It lands exactly on the truth. Always run this test on any reward you invent. It takes a minute and it would have saved us days.
We use G = 8 outcomes per item, and the outcomes are sampled from the data, not from the model. The model never gets told the true odds directly. It only sees what happened.
Where do the "true odds" come from?
For normal labeled data, the target is one-hot (the label happened with probability 1). But a calibration model also needs to see cases that are genuinely uncertain, otherwise it only ever learns "be 100% sure".
So we generate ambiguous items with soft labels. For example, a short log where two options fit the evidence equally well has the target [0.5, 0.5], and the right behavior is to say 0.5. We mix certain and ambiguous items (about 40% certain in the final runs) and give ambiguous items more weight in the loss, so the certain majority does not drown them out.
The KL anchor mistake
A lot of RL recipes add a KL penalty that keeps the model close to where it started. We added one too. It made things worse.
Here is why: a KL penalty is a pull toward the old model's answers. That is a second target competing with the truth, so the best answer is no longer the truth. It is somewhere between the truth and the old model. Our model got less sharp: it stopped separating easy cases from hard ones.
The rule we ended up following for anything added to the loss: at the point where the model's probabilities equal the truth, the extra term must have zero gradient. If it does not, it moves the optimum. The KL anchor fails that test, so we set its weight to 0.
Two smaller things that bit us
-
Brier vs log score. Before the RL reward, we trained Stage 3 with a direct loss against the soft labels, and we started with Brier. Brier is proper, but its gradient gets tiny when the model is very confident. At 0.999 confidence it is about 250 times smaller than the log score's gradient, so an overconfident model barely gets corrected. Our RL reward is built on log scores, which avoids this.
-
Clip gradients. The log score can give big gradients in exactly the overconfident cases you are trying to fix. One unclipped spike can wreck a run.
Step 7: Measuring calibration correctly
You cannot improve what you measure wrong. And we measured it wrong for a while.
Reliability and resolution
Accuracy alone is not enough. We split the Brier score into two parts (this is called the Murphy decomposition):
-
Reliability: how far confidence is from actual accuracy. Lower is better. This is calibration.
-
Resolution: how well confidence separates right answers from wrong ones. Higher is better.
Why both? A model that always says "70%" on a task where it is right 70% of the time has perfect reliability. But it is useless, because it cannot tell easy cases from hard ones. Resolution catches that.
def murphy(rows, bins=10):
    """rows: list of (confidence, correct) pairs."""
    n = len(rows)
    base = sum(o for _, o in rows) / n
    groups = [[] for _ in range(bins)]
    for c, o in rows:
        groups[min(bins - 1, int(c * bins))].append((c, o))
    rel = res = 0.0
    for g in groups:
        if not g:
            continue
        conf = sum(c for c, _ in g) / len(g)
        acc = sum(o for _, o in g) / len(g)
        rel += len(g) / n * (conf - acc) ** 2
        res += len(g) / n * (acc - base) ** 2
    return rel, res
Selective accuracy
This is the number that matters in practice: if I only act when the model is at least 0.9 confident, how accurate is that slice, and how much of my data does it cover?
def selective(rows, thr=0.9):
    hi = [(c, o) for c, o in rows if c >= thr]
    return dict(coverage=len(hi) / len(rows),
                accuracy=sum(o for _, o in hi) / len(hi),
                promised=sum(c for c, _ in hi) / len(hi))
If accuracy is close to promised, you can trust the threshold.
The metric bug
For ambiguous items, we first counted an answer as "correct" if it matched the most likely label. That sounds fine, but think about an item with odds [0.55, 0.45]. An honest model says 0.55. It picks the first option and is "correct" 100% of the time by our metric, so its 0.55 confidence looks badly under-confident. An overconfident model that says 0.99 looks perfect.
Our metric was rewarding exactly the behavior we were trying to remove. In numbers: the honest model scored a reliability error of 0.1019, the overconfident one scored 0.0001.
The fix: on ambiguous items, "correct" is the true probability of the picked option, soft[pred], not a 0/1 match.
correct = soft[pred] # not: 1.0 if pred == argmax(soft) else 0.0
After fixing it we had to re-measure every checkpoint, and some conclusions we had already written down flipped.
Step 8: Guard the stages
Stage 3 is supposed to teach decisions, not format. But RL updates the same LoRA weights, so it can slowly erase what Stage 2 taught.
So during Stage 3 we keep running a structure probe: fresh content-free questions that were never trained on. If that accuracy moves by more than 0.01 either way, something is wrong:
-
If it goes down, Stage 3 is overwriting Stage 2.
-
If it goes up, Stage 2 was not actually finished.
We also put a hard check in the training script that crashes if any structure-only data ends up in the Stage 3 training set. Stages that are supposed to be separate should be separate in code too, not just in our heads.
Step 9: Export to a normal Hugging Face model
Training happened on a 4-bit base with LoRA, which only runs in MLX. To publish, we:
-
Merge each LoRA into its layer. You cannot add a float update to packed 4-bit weights, so we dequantize first: W = dequantize(W_q) + scale * B @ A.
-
Dequantize every other layer to bf16.
-
Rename our scorer to score.weight and save it as a Qwen3ForSequenceClassification with one label.
That last part works because our branch readout is mathematically the same thing as running each option as its own full sequence and reading a score from its last token. That is exactly what Hugging Face's sequence classification head does. Our trick only makes it faster by sharing the prefix.
from mlx_lm.utils import dequantize_model
from mlx.utils import tree_flatten, tree_unflatten

fused = [(n, mod.fuse(dequantize=True)) for n, mod in m.backbone.named_modules() if hasattr(mod, "fuse")]
m.backbone.update_modules(tree_unflatten(fused))
bb = dequantize_model(m.backbone)

weights = {k: v.astype(mx.bfloat16) for k, v in tree_flatten(bb.parameters())}
weights.pop("lm_head.weight", None)               # tied embeddings, no LM head needed
weights["score.weight"] = m.scorer.weight.astype(mx.bfloat16)
mx.save_safetensors("gero-4b/model.safetensors", weights, metadata={"format": "pt"})
# plus config.json with architectures=["Qwen3ForSequenceClassification"], num_labels=1
Then verify. We loaded only the exported files and compared against the training checkpoint on 1,866 held-out items. The top answer matched on 98.8% of them, and the small differences were the same size as normal numerical noise.
Mistakes we made (so you do not have to)
-
A 256-slot head where only 6 slots ever got trained.
-
Negation words that only appeared in negated questions, so the model learned a flip shortcut.
-
Wrong answers that were not in the state, so "is it mentioned?" solved the task.
-
Multiplying gradients to get a higher learning rate under Adam. It cancels out.
-
A naive RL reward that was not proper and pushed the right answer to 0.001.
-
A KL anchor that moved the optimum away from the truth.
-
A calibration metric that rewarded overconfidence on ambiguous items.
The model is on Hugging Face at vixhal-baraiya/Gero-4B if you want to try it.
Keep building. Keep learning.


