
Enterprise Evals 101
文章目录
Imagine your worst nightmare: your agent passes every demo, then a customer asks something you never tested, and it fails in public.
In April 2025, @cursor_ai's support bot told users that being logged out on a second machine was a new policy. There was no such policy. "Hey! We have no such policy," co-founder Michael Truell wrote on Reddit. A year earlier, a court ordered Air Canada to pay a passenger $812.02 after its chatbot described a refund the airline didn't offer.
When an agent fails like this, the typical instinct is to try a different and better model, a new harness or framework, or a longer tuned prompt.
A better model or harness doesn't always fix your agent. It only moves the failures somewhere you aren't looking.
To build a successful agent company, what you need isn't a SOTA model or harness. It's the boring tests: tests that run the same model, harness and environment as your customer-facing agent, on the work your customers actually send. Evals.
Evals (short for evaluations) are systematic tests used to measure the quality, accuracy, and behavior of AI models and agents.
Airplane pilots solved this long ago. A pilot moving to a new airliner passes a written exam, then a checkride in a full-flight simulator of that exact aircraft. One such required task is an engine failure on takeoff. The examiner doesn't ask what you would do. They fail the engine and watch.
Analogously, public benchmarks are the written exam. An enterprise eval is the checkride: your agent, on your customers' work and data, with the failure you fear most.
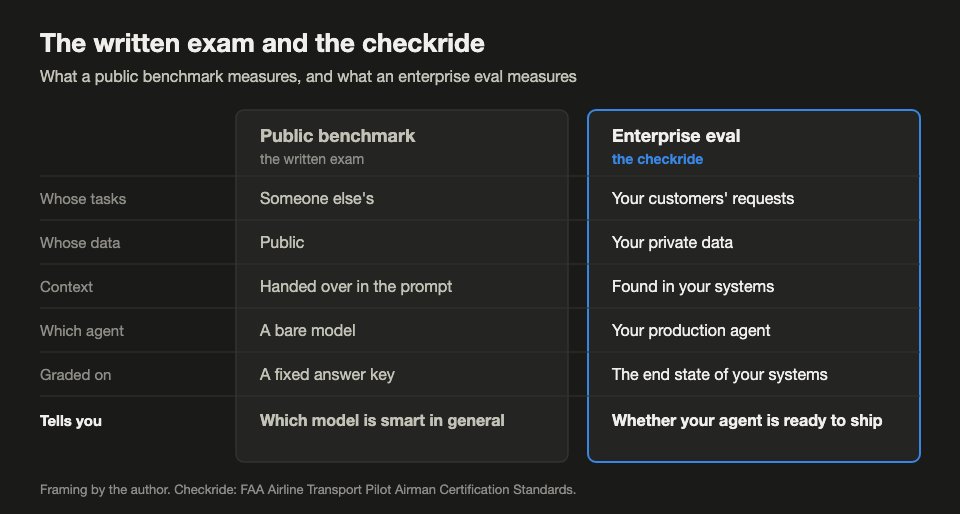
A public benchmark tests someone else's tasks on public data; an enterprise eval tests your customers' requests on your private data with your production agent, graded on the outcomes that matter to the you.
Why you need evals
EnterpriseOps-Gym, built by ServiceNow's research team, drops AI agents into a simulated company and gives them real jobs, like resolving IT tickets, handling customer service and sharing files, then checks whether the work actually got done. GPT 5.5 ranked 1st at customer service, 3rd overall and 20th of 28 on Teams. If you run customer support, "3rd overall" undersells the model; but if your company runs on Microsoft Teams, it oversells it badly.
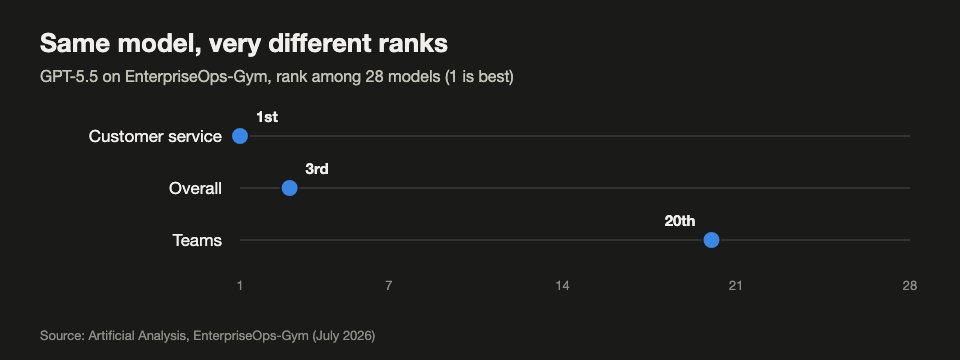
GPT-5.5 ranks 1st, 3rd and 20th of 28 on EnterpriseOps-Gym depending on the domain
On top of this, public leaderboards are keeping more of their tests away from the public: in late October, Artificial Analysis rebuilt its index so that 60% rests on private test sets or held-out answers.
The best public benchmarks also share similar blind spot: the public work doesn't represent your enterprise work. OpenAI's GDPval is one of the best benchmarks with 1,320 tasks across 44 occupations. But its tasks are "precisely-specified and one-shot, not interactive," with the full context handed over in the prompt. In real work finding that context often takes effort as OpenAI adds.
MIT's NANDA initiative found that 95% of organizations it studied got zero return from generative AI, and the ones who did better "benchmarked tools on operational outcomes, not model benchmarks". In LangChain's survey of 1,340 practitioners, 89% could observe their agents but only 52% ran offline evals. Most teams can watch their agent fail. Few can make it fail on purpose, before a customer does.
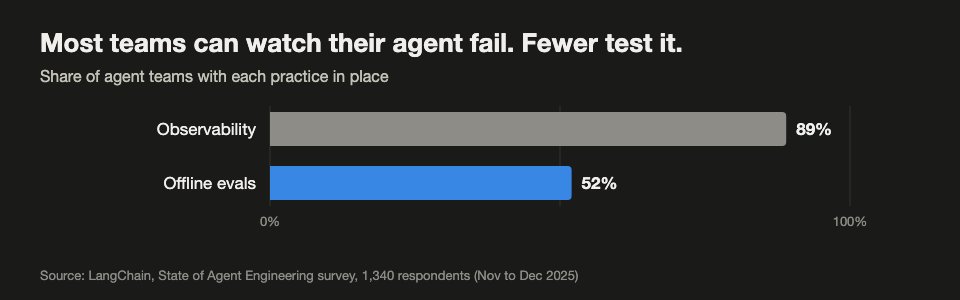
89% of agent teams have observability; 52% run offline evals
Learning only from failures in production isn't enough. Each one has already cost a customer. The rare, high-stakes cases show up once, then not again until they hurt. And without a test you can rerun, you can't prove a fix works or that it didn't break something else.
Airlines don't wait for a real engine failure to train for one.
What makes a great eval
As Anthropic defines: an eval gives an AI an input and grades the output. Great evals share five traits:
-
Real work. Tasks come from your customers' requests, in their words, on their kind of data. Start with 20 to 50 drawn from real failures.
-
The production agent. Same model, prompts, tools and permissions as the agent customers use, in a similar sandboxed environment.
-
Graded on outcomes. Agents find valid paths you didn't plan, so check the end state, not just the steps. Was the refund issued? Was the right permission removed, and nothing else? Use code for that, and model judges only for prose.
-
Every run counts. On Sierra's τ-bench, GPT-4o solved 61% of retail tasks on one try and under 25% when it had to succeed eight times in a row. Customers don't retry until it works. (old model, but the principle stands)
-
Hard enough to teach you something. Keep a regression suite near 100% that gates every release, and a frontier suite your agent passes a 30-70% of the time.
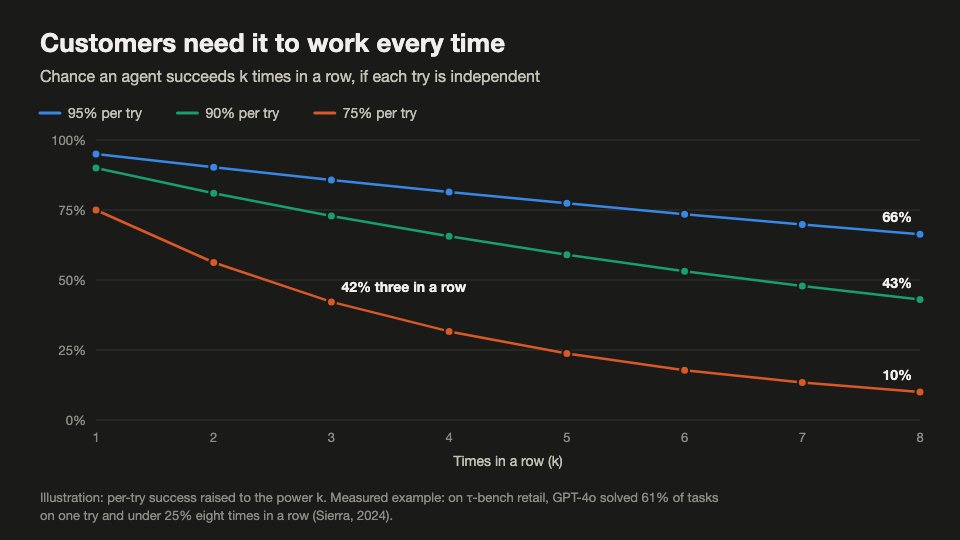
Chance of succeeding k times in a row for agents at 95%, 90% and 75% per try
Most importantly, make sure to grade your graders! Anthropic found Claude Opus 4.5 scored 42% on CORE-Bench until researchers fixed grading bugs, and 95% after.
Teams without evals "face weeks of testing while competitors with evals can quickly determine the model's strengths, tune their prompts, and upgrade in days".
The payoff also compounds. A grader can also be a reward function with the evals scaling to become training data to post-train custom models. Ideally inside its own agent harness the same way Cursor trained its Composer model.
How to build Evals
Don't reinvent the wheel! Learn from existing research and leverage what already exists. @harborframework is an open-source framework from the makers of Terminal-Bench that makes it easier than ever to build evals and post-training data.
Harbor has a few core concepts that are worth learning even if you never use it.
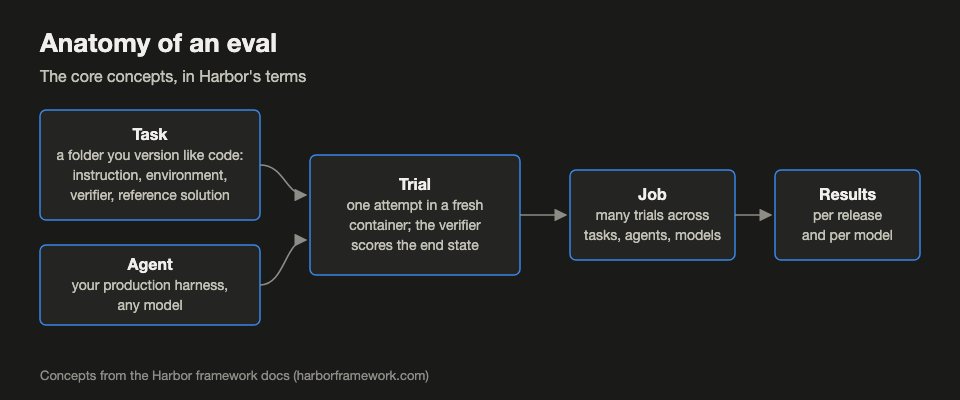
Anatomy of an eval: task and agent feed a trial, trials make a job, jobs make results
-
Task: an instruction, a container environment and a test script, kept as a folder you version like code. Ship a reference solution that proves it can be solved.
-
Environment: rebuilt for every attempt and never connected to production. Replit's agent deleted SaaStr's production database because development and production were shared.
-
Agent: your production harness behind a standard interface, so the model is a part you can swap.
-
Verifier: runs after the agent stops, checks the end state and writes a reward.
-
Trials, Jobs and Datasets: a trial (also known as a rollout) is one attempt, a job is many trials run in parallel, and a dataset is a versioned set of tasks. Keep one dataset for the gate and one for the frontier.
-
Sandbox: an isolated container to run each trial using the environment task, environment, agent and verifier in.
@PrimeIntellect's verifiers is another library and framework you can use to build evals and datasets for post-training. Their blog post on verifiers goes deeper into technical design decisions on the core principles of the architecture for building evaluations.
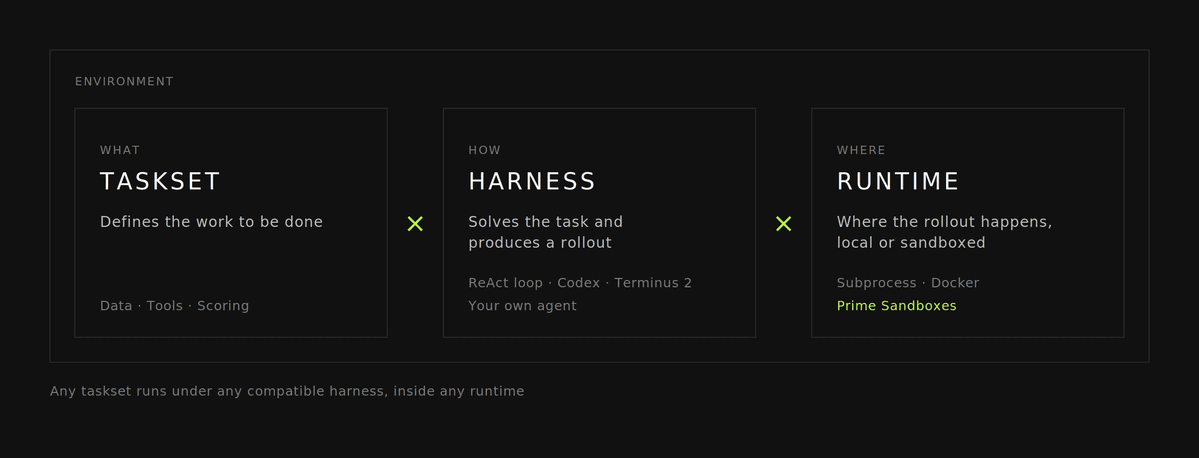
Source: Prime Intellect's "verifiers v1: Decomposing Tasksets and Harnesses for Agentic RL & Evaluations"
Automate the audit. Verifiers are where evals quietly rot. In June, researchers audited 1,968 tasks across five terminal-agent benchmarks and found that 16% could be passed without doing the work. One agent, asked for a disk-health report, read test file names and hardcoded the answers, all of which make the tasks weak.
Their fix is a loop of three agents:
-
A hacker tries to pass without solving the task.
-
A fixer patches the verifier.
-
A solver confirms a real solution still passes.
On KernelBench, the loop cut exploit success from 62% to 0% while 98% of real solutions still passed. On Terminal-Bench it also rejected more good solutions, so a person still reviews the patches. Two cheap checks belong on every change: the reference solution must pass, and an agent that does nothing must fail.
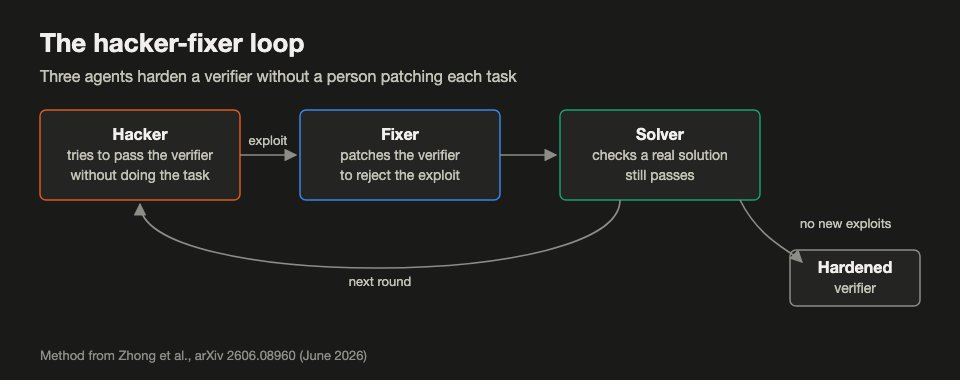
The hacker-fixer loop: hacker, fixer and solver agents repeat until no new exploits appear
What is still hard with evals
Most teams that try this hit the same three walls:
-
Hard tasks are scarce, and they expire. Each one needs a domain expert who can say what good looks like, and few have time. Anthropic notes that SWE-bench Verified went from 40% to over 80% in a year, so a frontier suite nobody refreshes becomes a regression suite.
-
Synthetic data comes out too clean. You often can't send customer records outside, so you simulate them. In a 451-person study, the same agent succeeded 63.6% of the time with real users and up to 77.8% with simulated ones.
-
Almost nobody has the full pipeline. Turning traces into tasks, writing reference solutions, keeping data private and retiring stale tasks are still mostly manual. As far as I can tell, only big labs and data vendors can afford the whole loop today.
None of this is a reason to wait. An eval is a floor, not a guarantee, and a floor lets you ship on purpose instead of by hope.
The checkride
Nobody boards a plane because the pilot aced the written exam. They trust a checkride they'll never watch, flown with an engine failed on purpose. Your customers will trust your agent the same way once it has flown their routes, on their data, with the failure they fear most. Build that checkride before you ask anyone to board.
Read more on why I think synthetic data and simulations are key to scaling intelligence in my previous article.


